中文 | English
# MiniCPM 3.0
MiniCPM 3.0 is a language model with 4 billion parameters. Compared to MiniCPM 1.0/2.0, it offers more comprehensive features and a significant improvement in overall capabilities. Its performance on most evaluation benchmarks rivals or even surpasses many models with 7B-9B parameters.
* **Supports Function Call🛠️ and Code Interpreter💻**: Achieved SOTA among models with fewer than 9B parameters on the [Berkeley Function Calling Leaderboard (BFCL)](https://gorilla.cs.berkeley.edu/leaderboard.html), outperforming GLM-4-9B-Chat and Qwen2-7B-Instruct.
* **Exceptional Reasoning Ability🧮**: In terms of math abilities, it outperforms GPT-3.5-Turbo and several 7B-9B models on [MathBench](https://open-compass.github.io/MathBench/). On the highly challenging [LiveCodeBench](https://livecodebench.github.io/), it surpasses Llama3.1-8B-Instruct.
* **Outstanding Instruction-Following in English and Chinese🤖**: Exceeds GLM-4-9B-Chat and Qwen2-7B-Instruct on English instruction following with [IFEval](https://huggingface.co/datasets/google/IFEval) and on Chinese instruction following with [FollowBench-zh](https://huggingface.co/datasets/YuxinJiang/FollowBench).
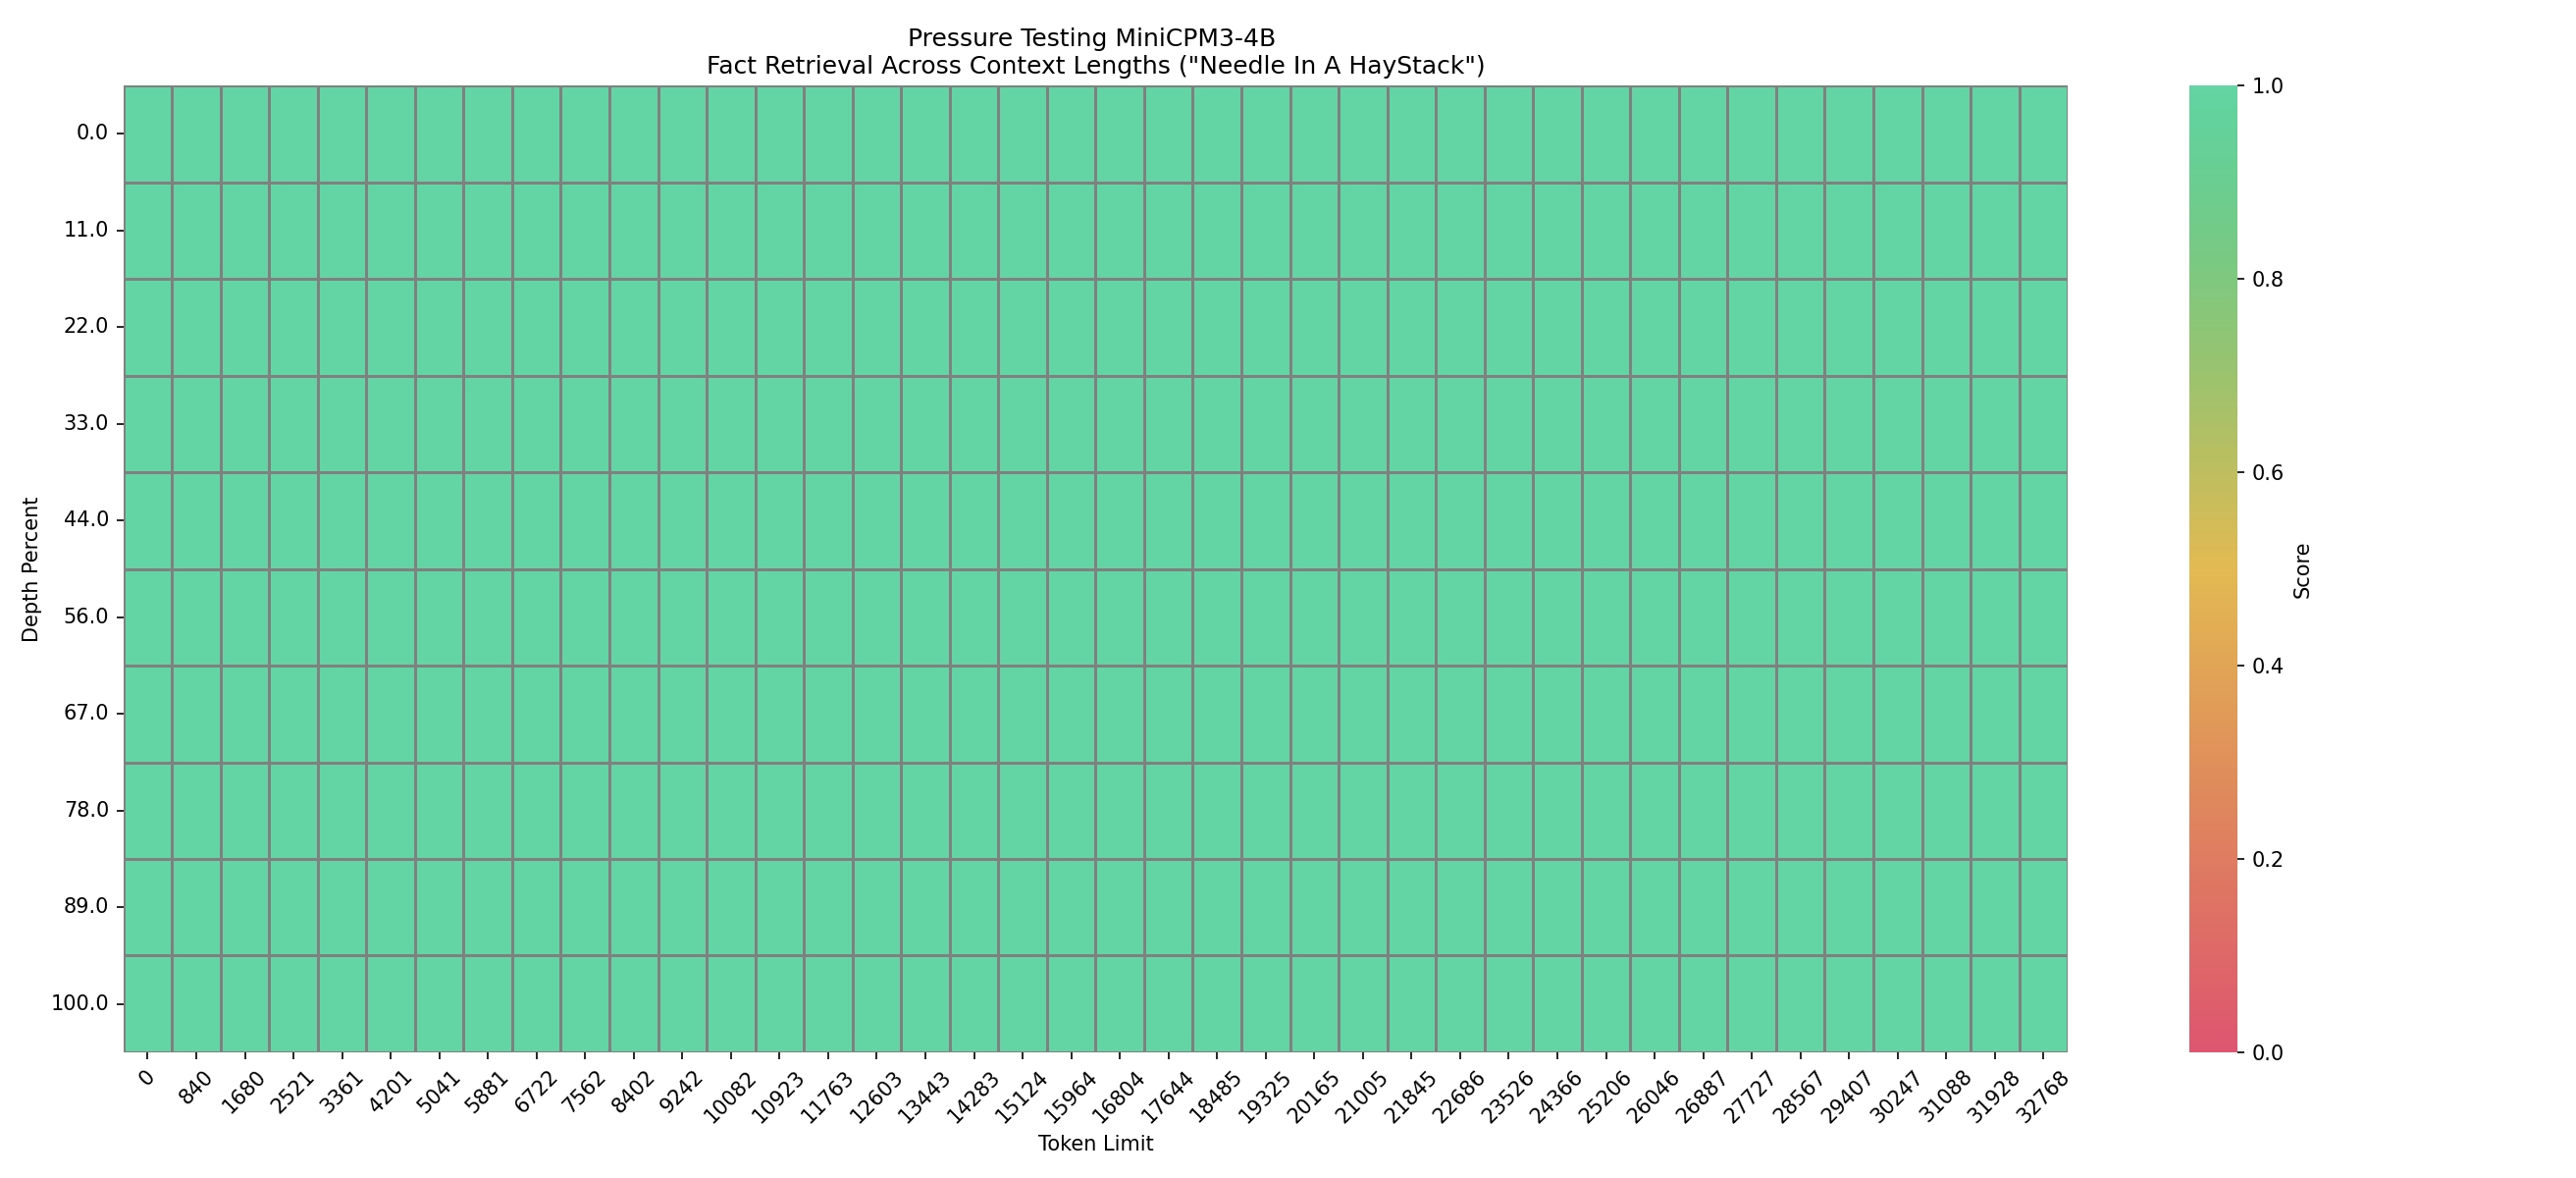
* **Long Context Capability**: Natively supports 32k context length, with flawless performance. We introduce the [LLMxMapReduce](https://github.com/thunlp/LLMxMapReduce) framework, theoretically enabling processing of context lengths up to infinity. Enhanced by LLMxMapReduce, MiniCPM3-4B achieves performance comparable to GPT-4 and KimiChat on InfiniteBench.
* **RAG Capability**:We release [MiniCPM RAG Suite](https://huggingface.co/collections/openbmb/minicpm-rag-suite-66d976b4204cd0a4f8beaabb). Based on the MiniCPM series models, [MiniCPM-Embedding](https://huggingface.co/openbmb/MiniCPM-Embedding) and [MiniCPM-Reranker](https://huggingface.co/openbmb/MiniCPM-Reranker) achieve SOTA performance on Chinese and Chinese-English cross-lingual retrieval tests. Specifically designed for the RAG scenario, [MiniCPM3-RAG-LoRA](https://huggingface.co/openbmb/MiniCPM3-RAG-LoRA) outperforms models like Llama3-8B and Baichuan2-13B on multiple tasks, such as open-domain question answering.
## Evaluation Results
### Comprehensive Evaluation
| Benchmarks |
Qwen2-7B-Instruct |
GLM-4-9B-Chat |
Gemma2-9B-it |
Llama3.1-8B-Instruct |
GPT-3.5-Turbo-0125 |
Phi-3.5-mini-Instruct(3.8B) |
MiniCPM3-4B |
| English |
| MMLU |
70.5 |
72.4 |
72.6 |
69.4 |
69.2 |
68.4 |
67.2 |
| BBH |
64.9 |
76.3 |
65.2 |
67.8 |
70.3 |
68.6 |
70.2 |
| MT-Bench |
8.41 |
8.35 |
7.88 |
8.28 |
8.17 |
8.60 |
8.41 |
| IFEVAL (Prompt Strict-Acc.) |
51.0 |
64.5 |
71.9 |
71.5 |
58.8 |
49.4 |
68.4 |
| Chinese |
| CMMLU |
80.9 |
71.5 |
59.5 |
55.8 |
54.5 |
46.9 |
73.3 |
| CEVAL |
77.2 |
75.6 |
56.7 |
55.2 |
52.8 |
46.1 |
73.6 |
| AlignBench v1.1 |
7.10 |
6.61 |
7.10 |
5.68 |
5.82 |
5.73 |
6.74 |
| FollowBench-zh (SSR) |
63.0 |
56.4 |
57.0 |
50.6 |
64.6 |
58.1 |
66.8 |
| Mathematics |
| MATH |
49.6 |
50.6 |
46.0 |
51.9 |
41.8 |
46.4 |
46.6 |
| GSM8K |
82.3 |
79.6 |
79.7 |
84.5 |
76.4 |
82.7 |
81.1 |
| MathBench |
63.4 |
59.4 |
45.8 |
54.3 |
48.9 |
54.9 |
65.6 |
| Coding |
| HumanEval+ |
70.1 |
67.1 |
61.6 |
62.8 |
66.5 |
68.9 |
68.3 |
| MBPP+ |
57.1 |
62.2 |
64.3 |
55.3 |
71.4 |
55.8 |
63.2 |
| LiveCodeBench v3 |
22.2 |
20.2 |
19.2 |
20.4 |
24.0 |
19.6 |
22.6 |
| Tool Use |
| BFCL v2 |
71.6 |
70.1 |
19.2 |
73.3 |
75.4 |
48.4 |
76.0 |
| Overall |
| Average |
65.3 |
65.0 |
57.9 |
60.8 |
61.0 |
57.2 |
66.3 |
### Function Calling
We evaluate the function calling capability of MiniCPM3 on [Berkeley Function Calling Leaderboard (BFCL)](https://gorilla.cs.berkeley.edu/leaderboard.html). MiniCPM3-4B outperforms several models with 7B-9B parameters on this leaderboard, surpassing GPT-3.5-Turbo-0125.
| Model |
Overall Accuracy |
AST Summary |
Exec Summary |
Irrelevance Detection |
Relevance Detection |
| MiniCPM3-4B |
76.03% |
68.55% |
85.54% |
53.71% |
90.24% |
| Llama3.1-8B-Instruct |
73.28% |
64.61% |
86.48% |
43.12% |
85.37% |
| Qwen2-7B-Instruct |
71.61% |
65.71% |
79.57% |
44.70% |
90.24% |
| GLM-4-9B-Chat |
70.08% |
60.69% |
80.02% |
55.02% |
82.93% |
| Phi-3.5-mini-instruct |
48.44% |
38.89% |
54.04% |
46.78% |
65.85% |
| Gemma2-9B-it |
19.18% |
5.41% |
18.50% |
88.88% |
7.32% |
### Long Context Capability
In the [Needle in a Haystack](https://github.com/gkamradt/LLMTest_NeedleInAHaystack) test with a context length of 32k, the results are shown as follows:
We also propose a divide-and-conquer long-sequence processing framework [LLMxMapReduce](https://github.com/thunlp/LLMxMapReduce) to support text with any length. MiniCPM3xMapReduce can achieve comparable performance with GPT-4 and KimiChat.
| | Context length| Qwen2-70b | Kimi-Chat(2024.06) | GPT-4 (From InfiniteBench) | MiniCPM 3.0 x MR | Qwen2-70b x MR | Llama3-70bx MR |
| ----------------------------- | ---------- | --------- | ------------------ | -------------------------- | --------------- | ------------ | ------------- |
| Math.Find | 87.9k | 59.71% | 18.57% | 60.00% | 83.43% | 54.29% | **91.43%** |
| Retrieve.KV | 89.9k | 29.00% | 69.20% | 89.00% | 93.80% | 98.80% | **98.89%** |
| En.Dia | 103.6K | 23.00% | 23.00% | 7.50% | 12.50% | **46.50%** | 17.50% |
| Code.Debug | 114.7k | 45.43% | 38.32% | 54.31% | 25.63% | 54.82% | **62.94%** |
| Retrieve.Number | 122.4k | **100.00%** | 97.45% | **100.00%** | 99.32% | **100.00%** | 99.79% |
| Retrieve.PassKey | 122.4k | **100.00%** | 99.32% | **100.00%** | 98.81% | **100.00%** | **100.00%** |
| En.Sum | 171.5K | 31.85% | 29.94% | 14.73% | 25.89% | **32.39%** | 30.63% |
| En.MC | 184.4k | 81.66% | 79.91% | 68.12% | 66.38% |**83.84%** | 82.10% |
| En.QA | 192.6k | 21.97% | 18.80% | 22.44% | 28.39% | 23.13% | **34.70%** |
| Zh.QA | 2068.6k | 21.40% | 19.84% | **25.96%** | 23.66% | 19.10% | N/A |
| avg w/o Zh.QA | / | 51.92% | 52.96% | 55.33% | 59.29% | 64.98% | **68.64%** |
| avg | / | 48.86% | 49.65% | 52.39% | 55.55% | **60.39%** | N/A |
## Inference
### Huggingface
```python
from transformers import AutoModelForCausalLM, AutoTokenizer
import torch
torch.manual_seed(0)
path = 'openbmb/MiniCPM3-4B'
tokenizer = AutoTokenizer.from_pretrained(path)
model = AutoModelForCausalLM.from_pretrained(path, torch_dtype=torch.bfloat16, device_map='cuda', trust_remote_code=True)
responds, history = model.chat(tokenizer, "Write an article about Artificial Intelligence.", temperature=0.7, top_p=0.7)
print(responds)
```
### SGLang (Recommended)
* Installation
Refer to SGLang [repo](https://github.com/sgl-project/sglang) to install the latest version *via source code*.
* Launch a server
```shell
python -m sglang.launch_server --model openbmb/MiniCPM3-4B --trust-remote-code --port 30000 --chat-template chatml
```
* Example code
```python
from sglang import function, system, user, assistant, gen, set_default_backend, RuntimeEndpoint
@function
def multi_turn_question(s, question_1, question_2):
s += user(question_1)
s += assistant(gen("answer_1", max_tokens=1024))
s += user(question_2)
s += assistant(gen("answer_2", max_tokens=1024))
set_default_backend(RuntimeEndpoint("http://localhost:30000"))
state = multi_turn_question.run(
question_1="Introduce artificial intelligence",
question_2="Write an article about it",
)
for m in state.messages():
print(m["role"], ":", m["content"])
```
### vLLM
* Install vllm
```shell
pip install "vllm>=0.6.2"
```
* Inference
```python
from transformers import AutoTokenizer
from vllm import LLM, SamplingParams
model_name = "openbmb/MiniCPM3-4B"
prompt = [{"role": "user", "content": "Write an article about Artificial Intelligence."}]
tokenizer = AutoTokenizer.from_pretrained(model_name, trust_remote_code=True)
input_text = tokenizer.apply_chat_template(prompt, tokenize=False, add_generation_prompt=True)
llm = LLM(model=model_name,
trust_remote_code=True,
tensor_parallel_size=1
)
sampling_params = SamplingParams(top_p=0.7, temperature=0.7, max_tokens=1024)
outputs = llm.generate(prompts=input_text, sampling_params=sampling_params)
print(outputs[0].outputs[0].text)
```
### llama.cpp
We have provided the [GGUF formats]((https://huggingface.co/openbmb/MiniCPM3-4B-GGUF)) of MiniCPM3, which can be used in llama.cpp.
* Install llama.cpp
```shell
git clone https://github.com/ggerganov/llama.cpp
cd llama.cpp
make
```
* Inference
```shell
./llama-cli -c 1024 -m minicpm3-4b-fp16.gguf -n 1024 --top-p 0.7 --temp 0.7 --prompt "<|im_start|>user\nWrite an article about Artificial Intelligence.<|im_end|>\n<|im_start|>assistant\n"
```
## Fine-Tuning
### LLaMA-Factory
We have supported fine-tuning MiniCPM3 using [LLaMA-Factory](https://github.com/hiyouga/LLaMA-Factory). For usage instructions, refer to [LLaMA-Factory Fine-tuning](https://modelbest.feishu.cn/docx/Z7USdW4lloZzkZxQ14icJ3senjb?from=from_copylink)."
## Advanced Features
We use [vLLM](#vllm) in the example code for the following advanced features.
### Function calling
We provide example code for using function calls with MiniCPM3:
```bash
cd demo/minicpm3/function_call
python function_call.py
```
If you want to start a function call service, use the following commands:
```bash
cd demo/minicpm3/function_call
pip install -r requirements.txt
python openai_api_server.py \
--model openbmb/MiniCPM3-4B \
--served-model-name MiniCPM3-4B \
--chat-template chatml.jinja \
--dtype auto \
--api-key token-abc123 \
--tensor-parallel-size 1 \
--trust-remote-code
```
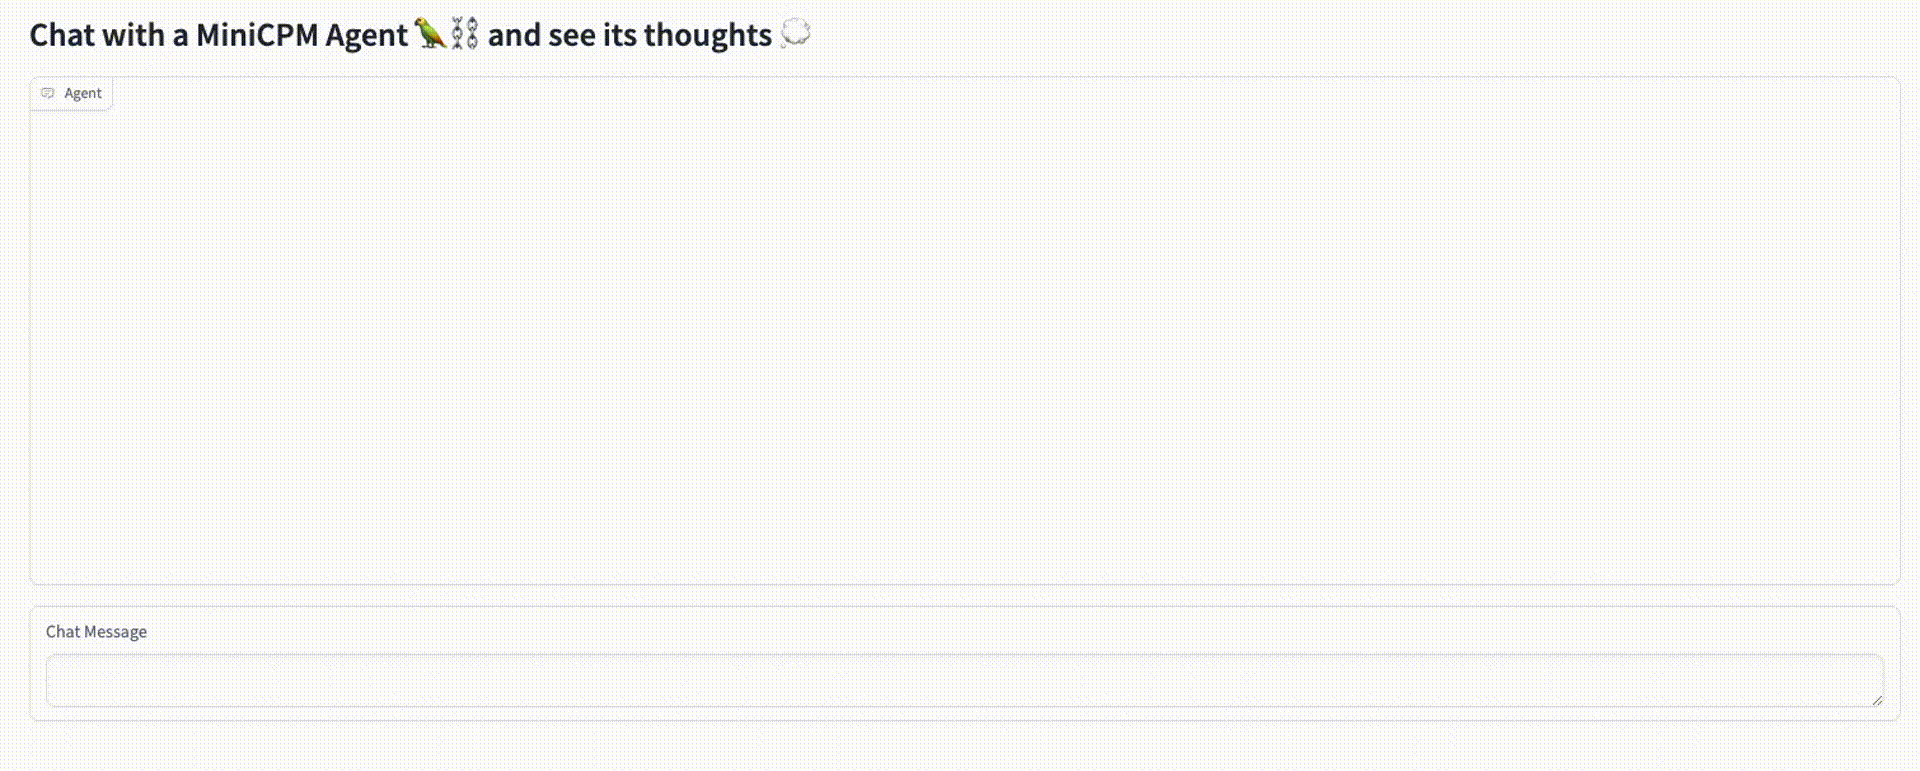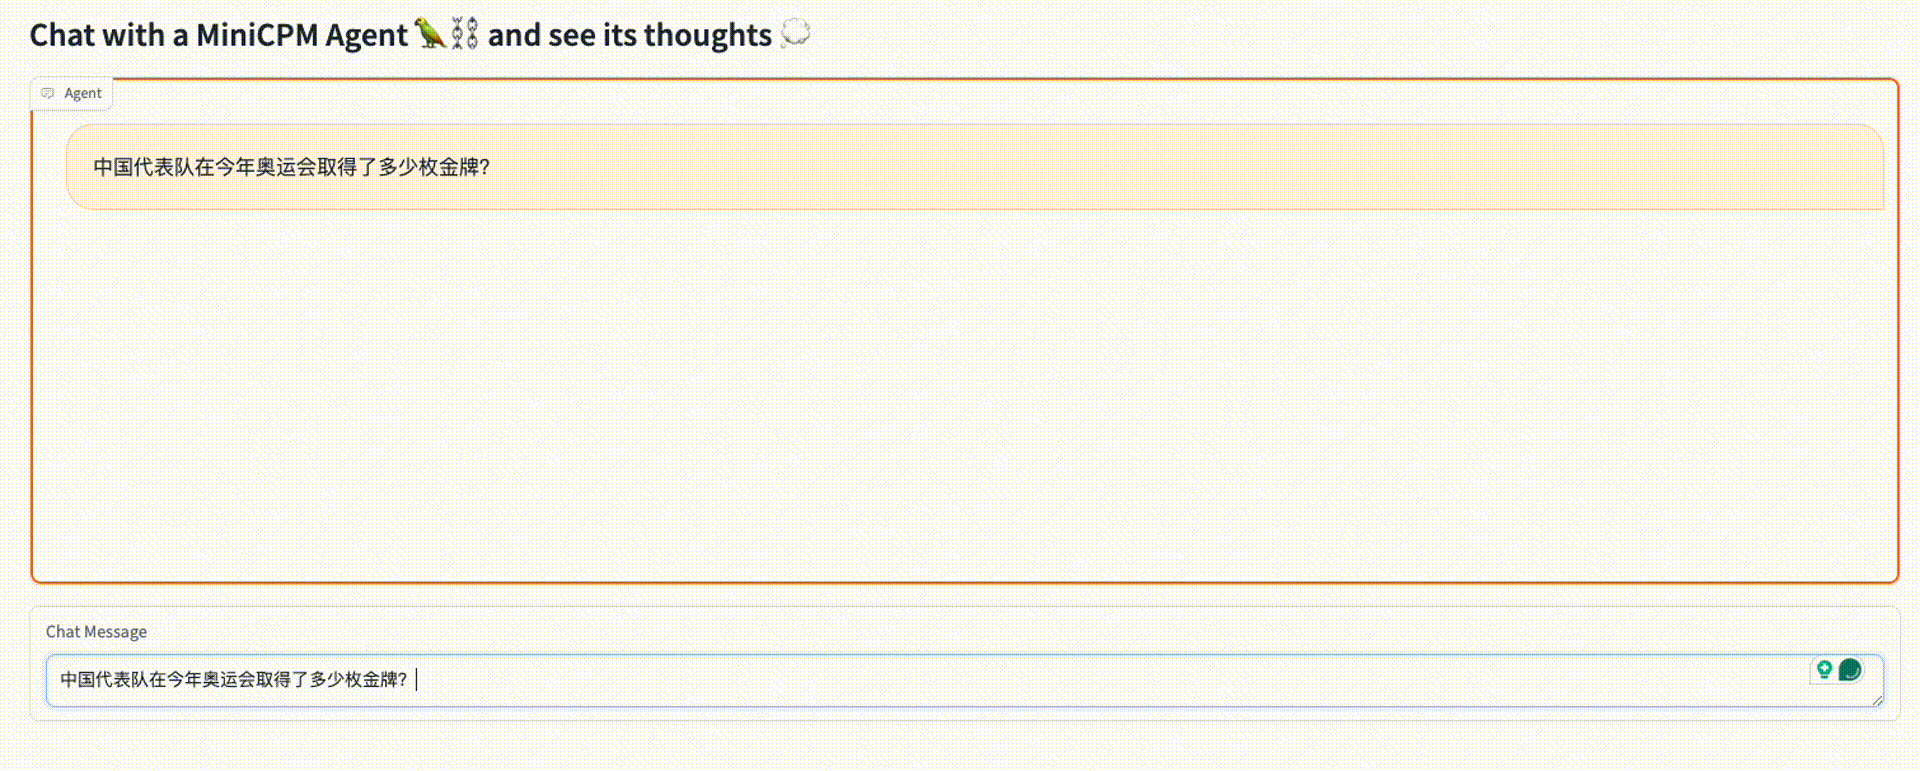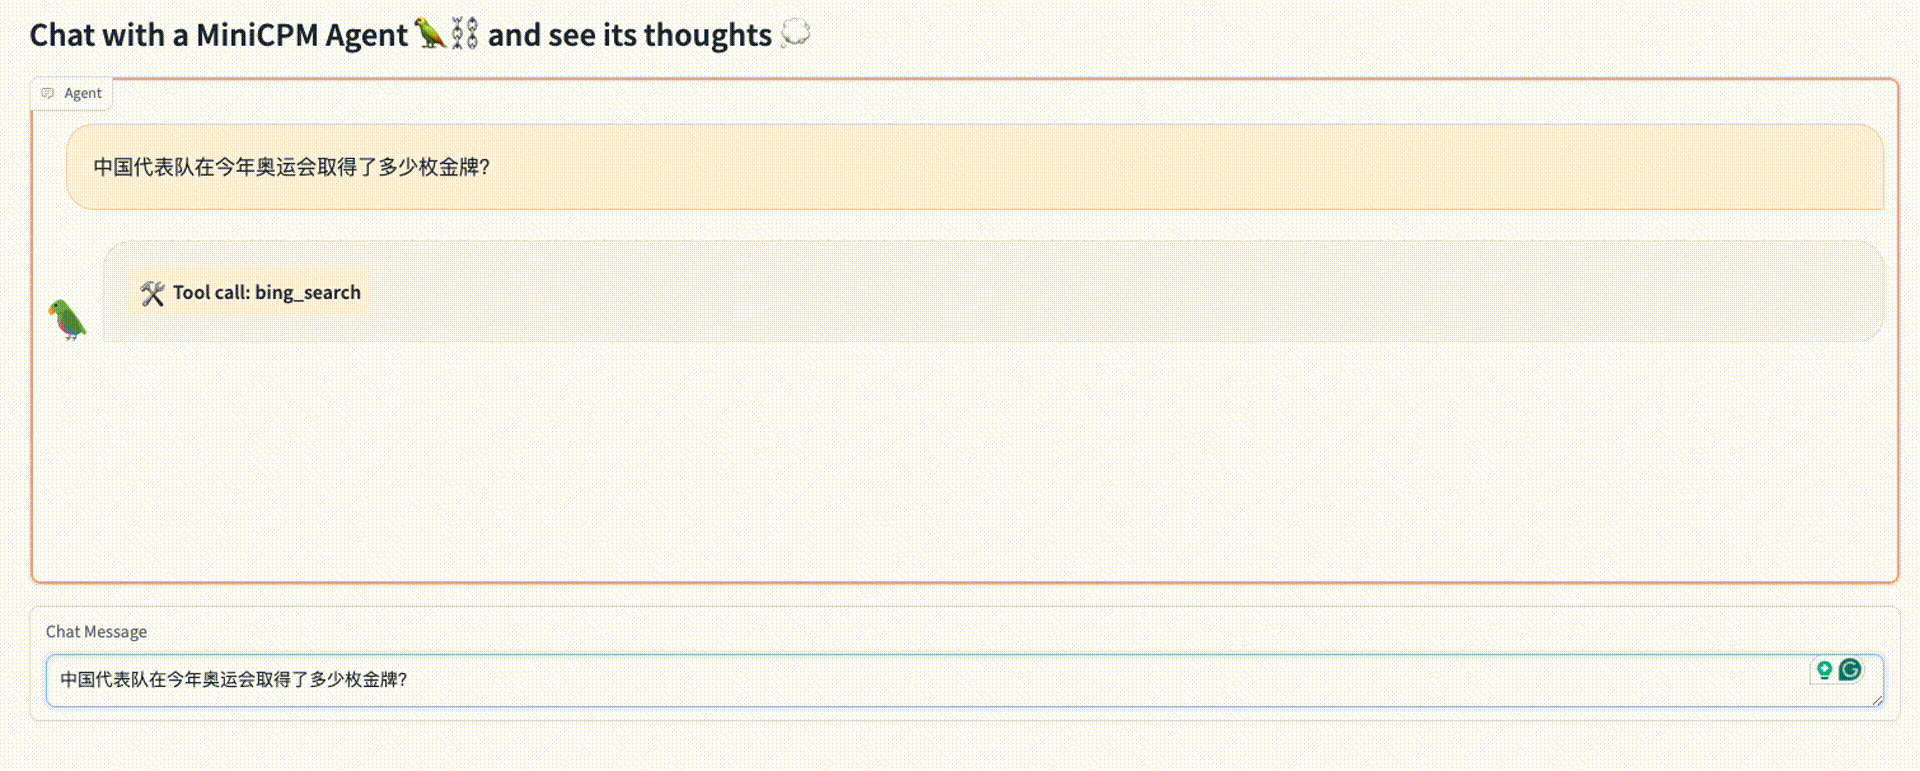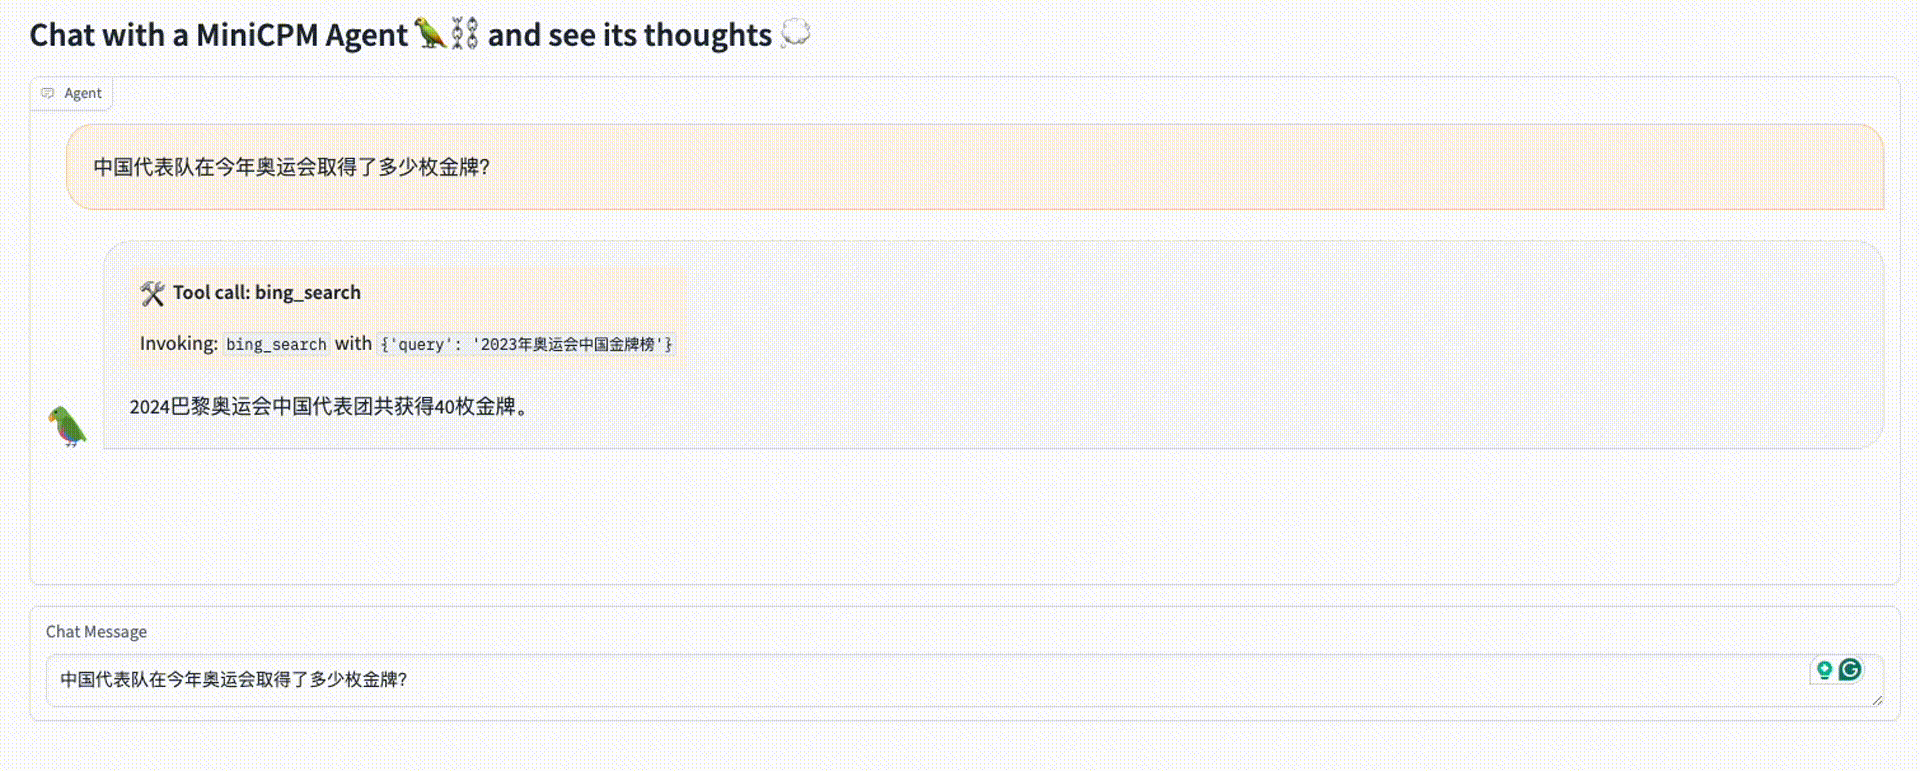
Below is a demo of using a search engine to answer the question:
### Code Interpreter
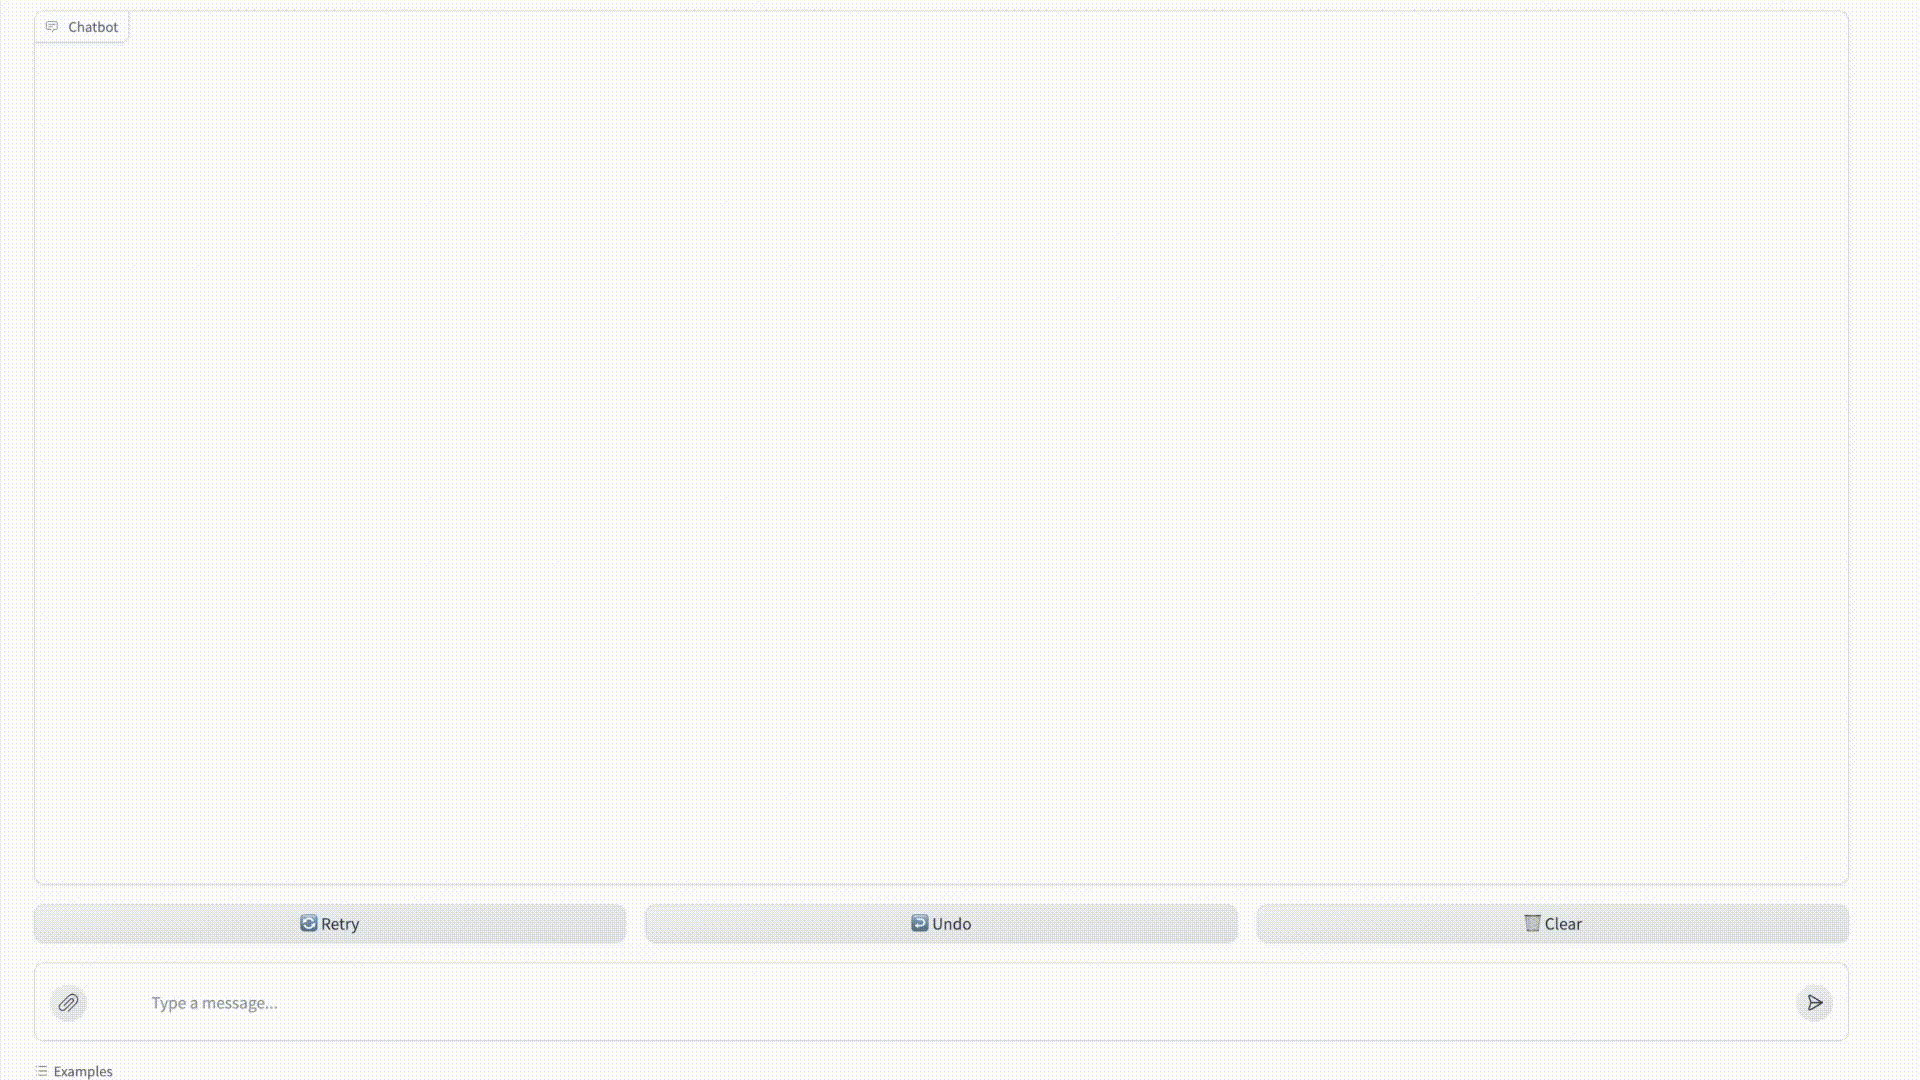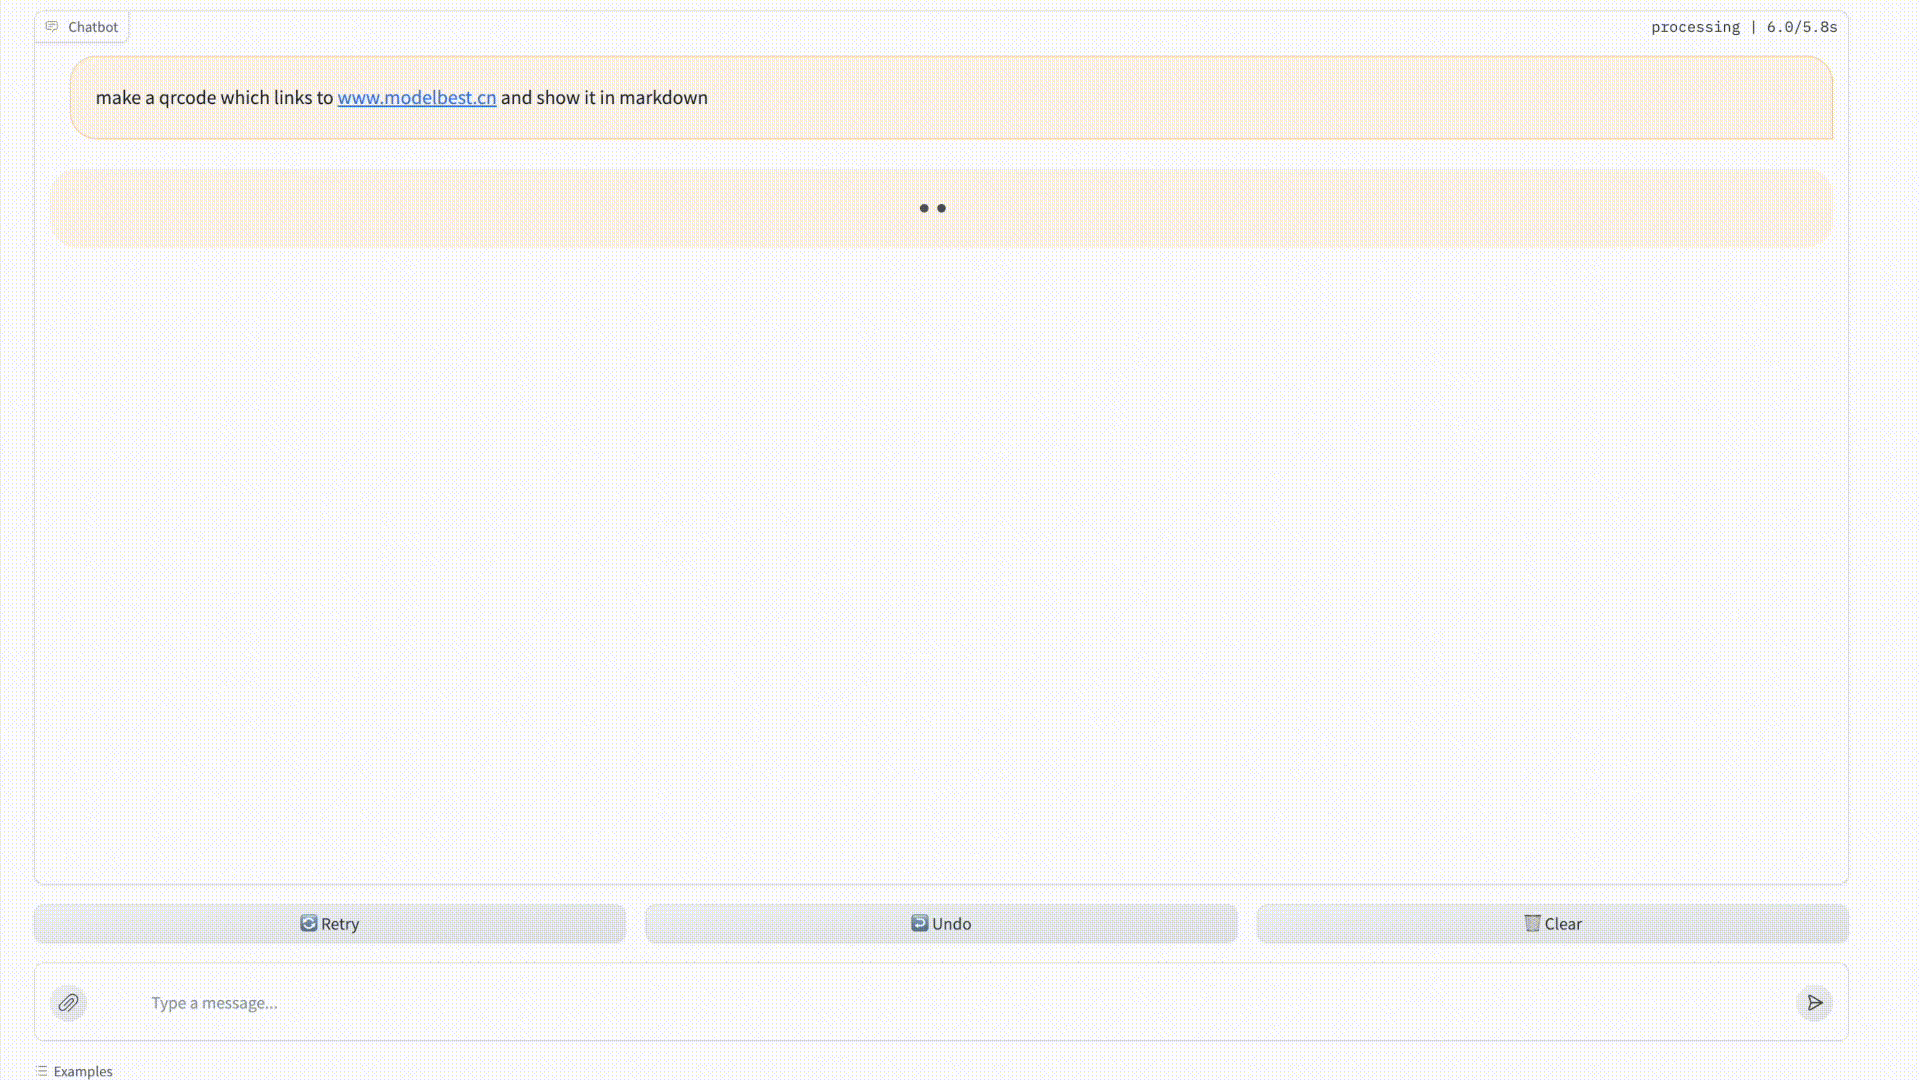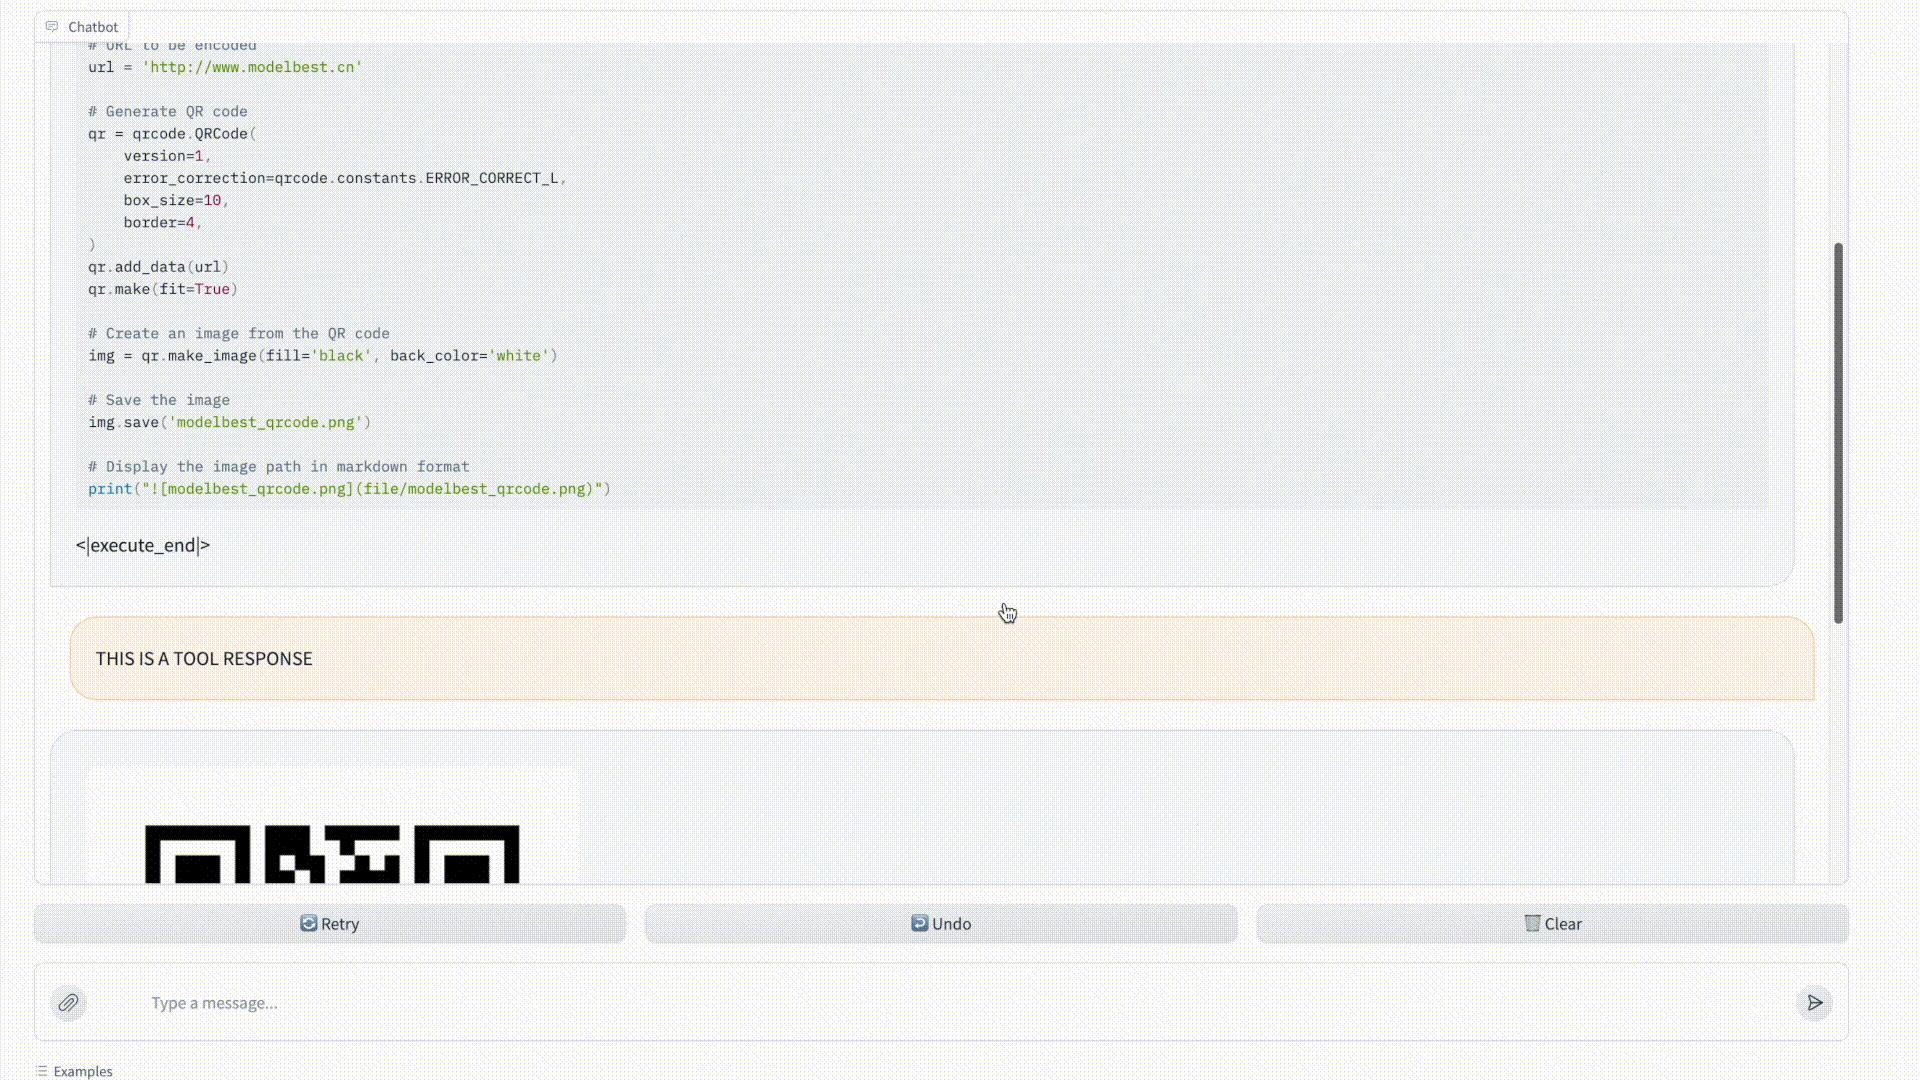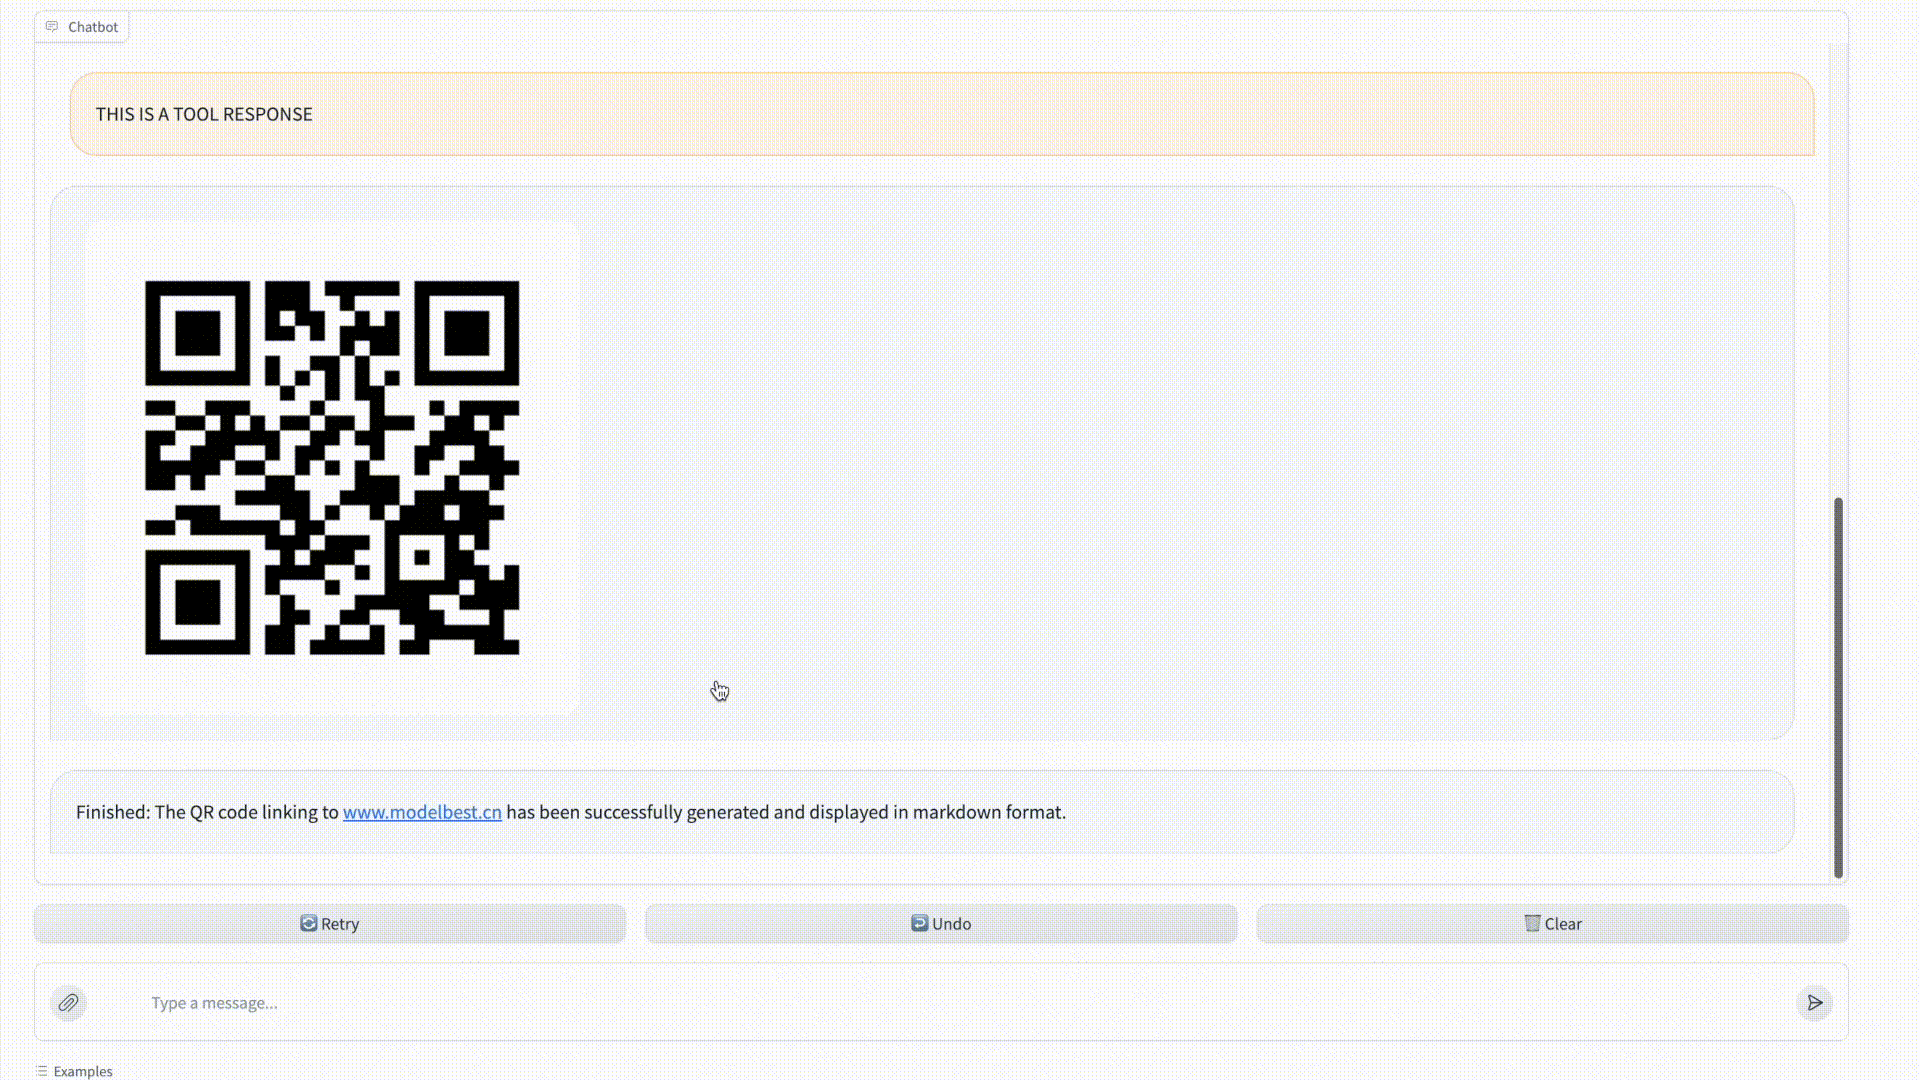
We provide example code for using the code interpreter with MiniCPM3:
```bash
cd demo/minicpm3/code_interpreter
pip install -r requirements.txt
python code_interpreter.py openbmb/MiniCPM3-4B
```
Below is an example of using the code interpreter to generate a QR code: