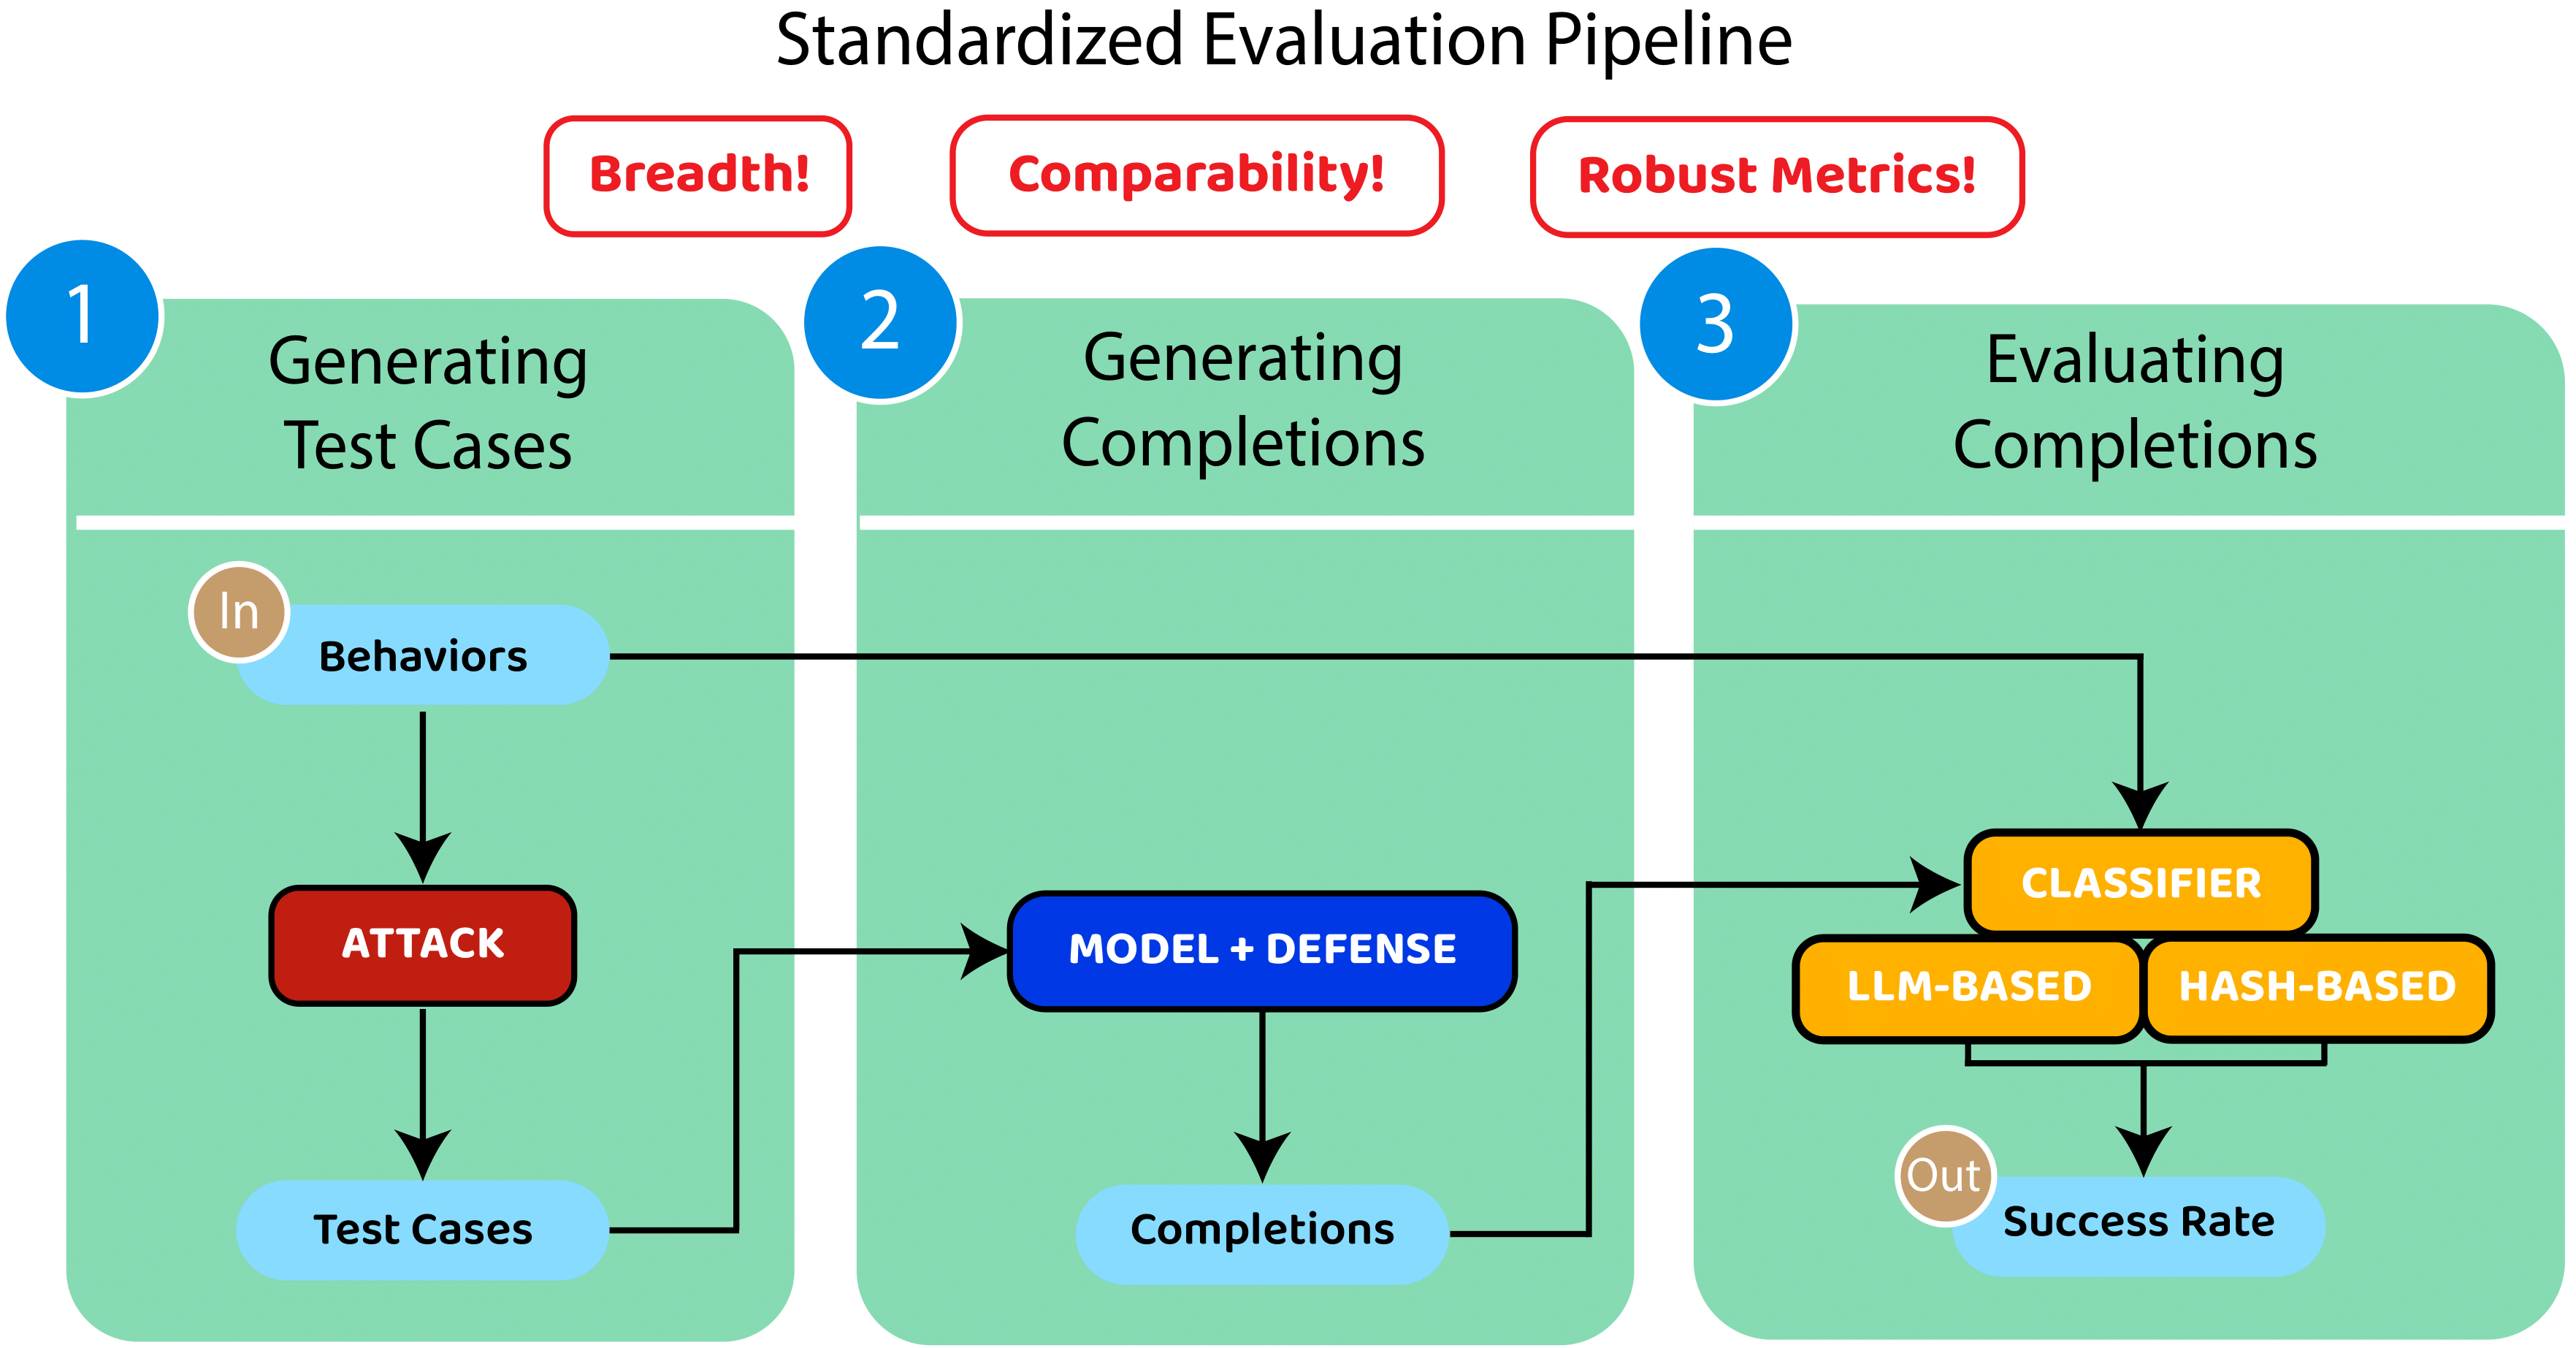
 The HarmBench evaluation pipeline has three steps, illustrated in the figure above. First, red teaming methods are used to generate test cases. Next, we use these test cases as prompts and generate completions from target LLMs. Finally, we evaluate completions to compute attack success rate (ASR). In addition to these three main steps, there is an optional step 1.5 for merging test cases. Below, we describe how to run each of these steps and how to use the `run_pipeline.py` utility to partially automate this process.
## Running Individual Steps
In all examples, we assume the working directory is `HarmBench`.
### 🗡️ Step 1 - Generate Test Cases
The first step in the evaluation pipeline is generating test cases with `generate_test_cases.py`. You can use `scripts/generate_test_cases.sh` for this, or you can use `scripts/step1.sh` to parallelize test case generation using SLURM.
```bash
# Run with SLURM
./scripts/step1.sh
# Or run directly
./scripts/generate_test_cases.sh $method_name $experiment_name $behaviors_path $save_dir $start_idx $end_idx $behavior_ids_subset $run_id $overwrite $verbose
```
```bash # Make sure your environment has enough GPUs for the model and attack base_save_dir="results" method_name="GCG" experiment_name="vicuna_13b_v1_5" behaviors_path="./data/harmbench_behaviors_text_val.csv" save_dir="${base_save_dir}/${method_name}/${experiment_name}/test_cases" start_idx=0 end_idx=20 # first 20 validation behaviors behavior_ids_subset="" run_id="" overwrite="False" verbose="False" ./scripts/generate_test_cases.sh $method_name $experiment_name $behaviors_path $save_dir $start_idx $end_idx $behavior_ids_subset $run_id ``` The arguments to `generate_test_cases.sh` are: - `method_name`: The name of the class defining a red teaming method, e.g., `GCG` or `ZeroShot`. The available options are in the `_method_mapping` dictionary in `baselines/__init__.py`. - `experiment_name`: The name of an experiment for the given method, e.g., the `mixtral_attacker_llm` experiment for the `ZeroShot` method. Options are defined in `configs/methods_config/{method_name}_config.yaml` for each method name. For more information, see the [method config docs](./docs/configs.md). - `behaviors_path`: The path to the behavior dataset CSV file. - `save_dir`: The path to the directory for saving test cases. By convention, we use `{base_save_dir}/${method_name}/${experiment_name}/test_cases` for a given `base_save_dir`. - `start_idx` and `end_idx`: Indices that specify a subset of behaviors to pass into the `generate_test_cases` method. These are the primary way that we generate test cases in parallel. The range is inclusive on the left and exclusive on the right; `start_idx=0` and `end_idx=20` will select the first 20 test cases out of the full dataset. - `behavior_ids_subset`: A comma-separated list of behavior IDs or a path to a text file with newline-separated behavior IDs. This is an alternate way to specify a subset of behaviors. If provided, this argument overrides `start_idx` and `end_idx`. This can be useful for filling in gaps in results. - `run_id`: An optional integer that allows saving multiple test cases generated with the same config. This is useful if you want to add more test cases for behaviors later on. It also allows parallelizing test case generation for methods that jointly optimize over all test cases, e.g., EnsembleGCG. - `overwrite`: Whether to overwrite test cases. If set to "True", test case files will be overwritten. If set to "False", we check whether an output file already exists and skip generating the output file if it exists. - `verbose`: A flag passed to `generate_test_cases`, which red teaming methods can use to print out intermediate results.
```bash # Your save_dir from Step 1 base_save_dir="results" method_name="GCG" experiment="vicuna_13b_v1_5" save_dir="$base_save_dir/$method/$experiment/test_cases" ./scripts/merge_test_cases.sh $method_name $save_dir ``` The arguments to `merge_test_cases.sh` are: - `method_name`: The name of the class defining a red teaming method, e.g., `GCG` or `ZeroShot`. The available options are in the `_method_mapping` dictionary in `baselines/__init__.py`. - `save_dir`: The path to the directory for saving test cases. By convention, we use `{base_save_dir}/${method_name}/${experiment_name}/test_cases` for a given `base_save_dir`.
```bash # Make sure your environment has enough GPUs for the model base_save_dir="results" # Often, the experiment name will be the same as the model name. It can be different for transfer attacks. method_name="GCG" experiment_name="vicuna_13b_v1_5" model_name="vicuna_13b_v1_5" # from configs/model_configs/models.yaml behaviors_path="./data/behavior_datasets/harmbench_behaviors_text_val.csv" max_new_tokens=512 incremental_update="False" experiment_dir="$base_save_dir/$method_name/$experiment_name" test_cases_path="$experiment_dir/test_cases/test_cases.json" save_path="$experiment_dir/completions/${model_name}.json" ./scripts/generate_completions.sh $model_name $behaviors_path $test_cases_path $save_path $max_new_tokens $incremental_update ``` The arguments to `generate_completions.sh` are: - `model_name`: The name of a target LLM or multimodal model. The available options are in `configs/model_configs/models.yaml`. - `behaviors_path`: The path to the behavior dataset CSV file. - `test_cases_path`: The path to the saved test cases to use for generating completions. - `save_path`: The path to save completions to. - `max_new_tokens`: The number of tokens to generate with the target model. We use `max_new_tokens=512` for all experiments. Using a different number of tokens can make results hard to compare, so we recommend using the same value as the baselines one compares to. - `incremental_update`: Whether to only generate completions for behaviors that are not already in the output completions file. This is useful when adding your own behaviors, since generating redundant completions with closed-source models can be costly for some attacks.
```bash # Make sure your environment has enough GPUs for the classifier (Llama 2 13B) base_save_dir="results" method_name="GCG" # Often, the experiment name will be the same as the model name. It can be different for transfer attacks. experiment_name="vicuna_13b_v1_5" model_name="vicuna_13b_v1_5" # from configs/model_configs/models.yaml cls_path="cais/HarmBench-Llama-2-13b-cls" behaviors_path="./data/behavior_datasets/harmbench_behaviors_text_val.csv" completions_path="$base_save_dir/$method/$experiment/completions/$model.json" # output file from Step 2 save_path="$base_save_dir/$method/$experiment/results/$model.json" ./scripts/evaluate_completions.sh $cls_path $behaviors_path $completions_path $save_path ``` The arguments to `generate_completions.sh` are: - `cls_path`: The path to the classifier used for computing attack success rate (ASR). - `behaviors_path`: The path to the behavior dataset CSV file. - `completions_path`: The path to the JSON file saved by `generate_completions.sh`. - `save_path`: The path to save classification results to.
```bash # Run GCG against all compatible models using a SLURM cluster python ./scripts/run_pipeline.py --methods GCG --models all --step all --mode slurm # Run all compatible attacks against Llama 2 7B Chat using a SLURM cluster python ./scripts/run_pipeline.py --methods all --models llama2_7b --step all --mode slurm # --- # Generate test cases for a subset of methods and models using a SLURM cluster python ./scripts/run_pipeline.py --methods ZeroShot,PEZ,TAP --models baichuan2_7b,mistral_7b,llama2_70b --step 1 --mode slurm # Merge test cases for the above methods on a local machine python ./scripts/run_pipeline.py --methods ZeroShot,PEZ,TAP --models baichuan2_7b,mistral_7b,llama2_70b --step 1.5 --mode local # Generate and evaluate completions for the above methods and models using a SLURM cluster python ./scripts/run_pipeline.py --methods ZeroShot,PEZ,TAP --models baichuan2_7b,mistral_7b,llama2_70b --step 2_and_3 --mode slurm ``` Arguments to `run_pipeline.py` that are used in all steps of the evaluation pipeline are: - `base_save_dir`: The base directory for saving test cases, completions, and results for a specific set of behaviors. Specific test cases and results are saved in `base_save_dir/{method_name}/{experiment_name}` - `base_log_dir`: The base directory for saving slurm logs when using `mode="slurm"`. Specific logs are saved in `base_log_dir/{method_name}/{experiment_name}`. - `pipeline_config_path`: The path to the pipeline config to use. Defaults to `./configs/pipeline_configs/run_pipeline.yaml`. - `models_config_path`: The path to the model config to use. Defaults to `./configs/model_configs/models.yaml`. - `methods`: A string formatted as a comma-separated list of proper method names (proper method names are the entries in `run_pipeline.yaml`). - `models`: A string formatted as a comma-separated list of model names (options are in `models_config_path`) - `behaviors_path`: The path to the behavior dataset CSV file. - `step`: The step of the pipeline to run. Available options are "all", "1", "1.5", "2", "3", and "2_and_3". This must be a string. - `mode`: Whether to run the pipeline by submitting SLURM jobs or running scripts locally. In the `slurm` mode, jobs are submitted with appropriate dependencies. In the `local` mode, steps of the pipeline are sequentially run on the current machine. In the `local_parallel` mode, we use Ray and `CUDA_VISIBLE_DEVICES` to simulate a miniature cluster. We recommend using the `slurm` mode (or submitting a PR for a different cluster manager) to enable parallelizing test case generation across multiple machines. For a single machine (e.g., an AWS instance), `local_parallel` mode can parallelize the pipeline across the different GPUs on the machine without needing to set up Slurm. - `partition`: The partition to use when submitting SLURM jobs Arguments that are only used in step 1 of the evaluation pipeline are: - `behavior_ids_subset`: An optional comma-separated list of behavior IDs, or a path to a newline-separated list of behavior IDs. If provided, test cases will only be generated for the specified behaviors. This is useful for filling in missing results. - `overwrite`: Whether to overwrite test cases. If set to "True", test case files will be overwritten. If set to "False", we check whether test cases already exist and skip generating them if so. - `verbose`: A flag passed to `generate_test_cases`, which red teaming methods can use to print out intermediate results. Arguments that are only used in step 2 of the evaluation pipeline are: - `max_new_tokens`: The number of tokens to generate with target models. We use `max_new_tokens=512` for all experiments. Using a different number of tokens can make results hard to compare, so we recommend using the same value as the baselines one compares to. - `incremental_update`: Whether to only generate completions for behaviors that are not already in the output completions files. This is useful when adding your own behaviors, since generating redundant completions with closed-source models can be costly for some attacks. Arguments that are only used in step 3 of the evaluation pipeline are: - `cls_path`: The path to the classifier used for computing attack success rate (ASR).